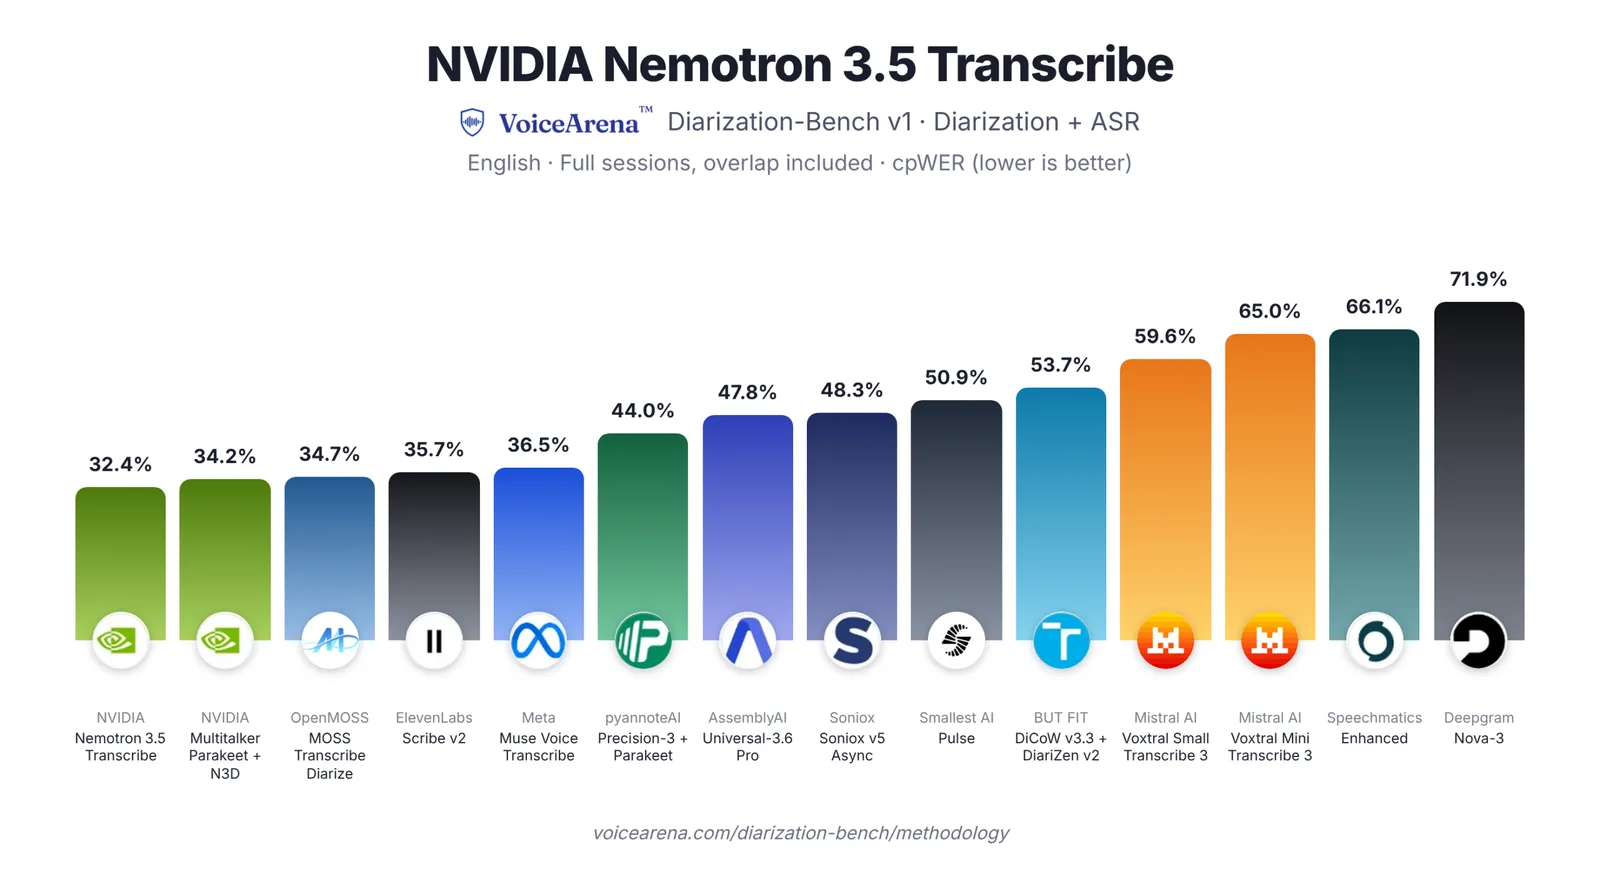
Nvidia has introduced an AI model for transcribing and translating audio.
The Tech AI
Get the key points in seconds - a short summary from The Tech AI.
Nvidia released the open-source Nemotron 3.5 Transcribe model for transcribing, translating, and analyzing audio recordings up to an hour long in 40 languages using a single GPU. The package includes the Granary v2 dataset with 48 languages for training models. The products are available on Hugging Face but do not support real-time recognition.
Nvidia has released Nemotron 3.5 Transcribe, an open-source AI model that transcribes audio recordings, translates speech, and identifies speakers. It can also generate brief meeting summaries and answer questions based on the content of the recordings.
The model supports 40 languages and allows multiple tasks to be performed with a single instruction. For example, it can prepare a meeting transcript with speaker names, translate a conversation into English, or extract key decisions.
Nemotron 3.5 Transcribe runs on a single Nvidia GPU. The model is suitable for processing recordings up to an hour long, involving multiple participants, including those who interrupt each other.
Alongside the model, the company introduced Granary v2, an open dataset of audio recordings in 48 languages. Developers can use it to train their own models and adapt speech recognition for specific domains, such as medicine.
Nemotron 3.5 Transcribe and Granary v2 are available on Hugging Face. The model works with pre-recorded audio files but does not yet support real-time speech recognition.
Source: huggingface.co
The Tech on Telegram Follow The Tech on Telegram
Keep up with the latest technology and startup news.
Related reading
More from this author
News IT
The launch of Global Tech Weekend 2027 will take place in Tbilisi.
The Tech
Article Useful
Business Cup, NASA Space Apps, and Startup Week: Opportunities for Startups in November 2026
The Tech
Article Startups
How a guy from Kashkadarya created an IT startup and attracted $40,000 in investments
The Tech
Article Useful
Free tickets to IT conferences in 2027: a list of international events
The Tech
Article Useful
10 platforms with free datasets for AI and machine learning
The Tech
News IT
Northwood Space has raised $375 million in investment to develop its satellite infrastructure.
The Tech