How to protect corporate data when employees use ChatGPT, Claude — TETRA Security solution
Employees are already using ChatGPT, Claude, and Gemini at work, but along with queries to AI services, corporate and personal data may also be sent. Meanwhile, businesses often do not see exactly what employees are sending.
The Tech AI
Get the key points in seconds - a short summary from The Tech AI.
The TETRA Security team from Tashkent has developed an on-premise solution for controlling the use of AI services (ChatGPT, Claude, Gemini) within the corporate perimeter. The system detects hidden data leaks by employees and applies monitoring, masking, or blocking policies in accordance with local regulatory requirements in Central Asian countries. Implementation begins with a monitoring mode to build an understanding of risks before transitioning to active protection measures.
The TETRA Security team from Tashkent has created a solution that shows what employees send to ChatGPT, Claude, and Gemini, and stops anything that shouldn’t leave the company perimeter. We explain how to integrate AI into business without losing control over data.
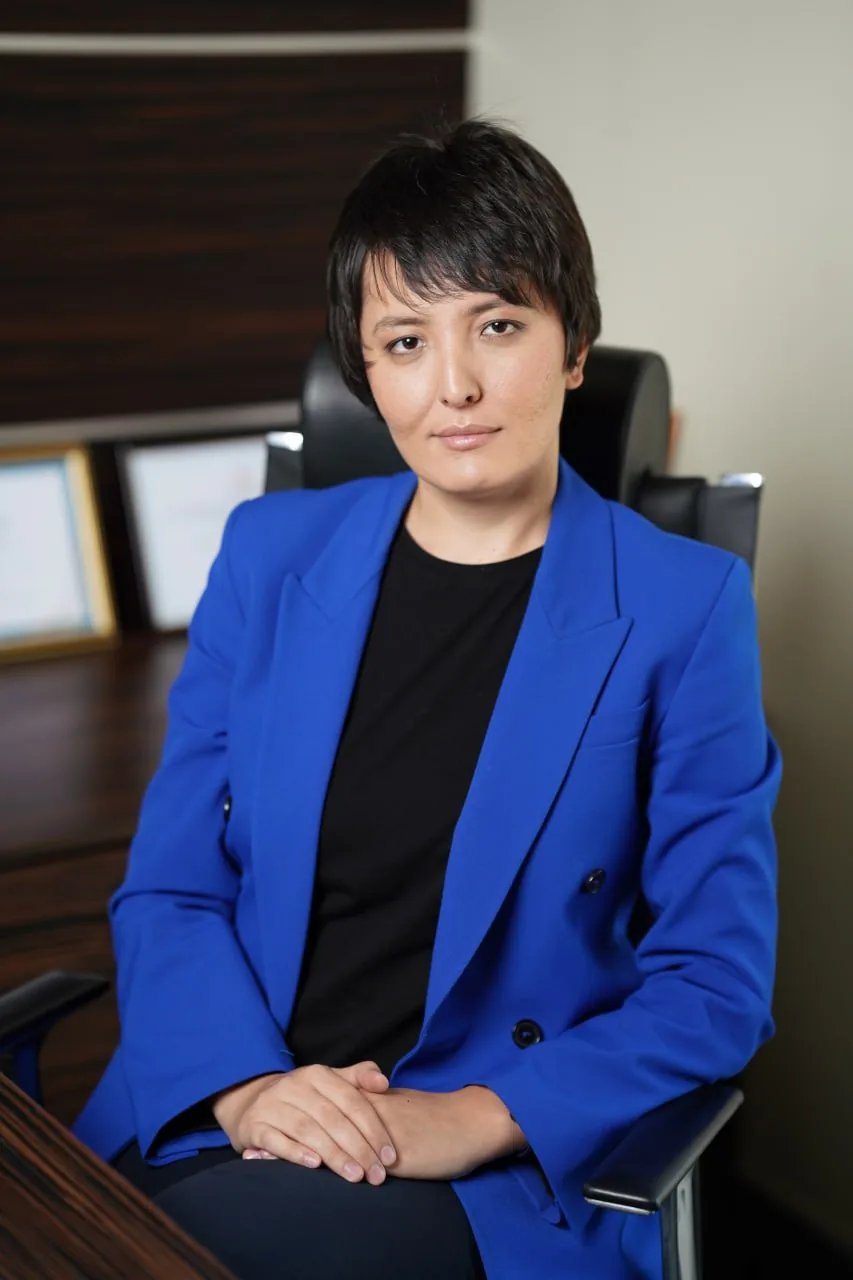
Sardor Ramazon, Tashkent, Chief Product Officer at TETRA Security, LinkedIn
How it all started
The idea came not from market analytics, but from practice. The founders of TETRA Security have over 10 years of experience in information security and IT, and at some point, each of us caught ourselves with an unpleasant thought: we were responsible for the company’s data, but had no idea what employees were sending to AI services on a daily basis.
The perimeter was secured according to all the rules. But a new channel had opened up nearby, and it wasn’t just open—it was invisible. Classic DLP solutions do not analyze what happens in a dialogue with ChatGPT or Claude.
When you spend 10 years building a perimeter and find a hole in it that the market barely talks about—you either wait for someone else to close it, or you close it yourself. We chose the second option.
What employees send to AI
Over the past two years, AI has become a standard work tool. A lawyer inserts an entire client contract, including amounts and details, into an AI service. An analyst uploads a dataset with personal data to generate a report faster. A developer sends a configuration file containing an active access key. None of them are intentionally violating rules: the employee simply wants to do their job faster.
This is exactly where a new hidden data leakage channel appears. Contracts with clients, personal data, fragments of source code, API keys, or other corporate information can end up in AI services.
The main problem is that the company often doesn’t even know this is happening.
Why this isn’t visible
For a company, this doesn’t always look like a classic data breach. A request to an AI service may appear as ordinary encrypted traffic to a legitimate service that employees are officially allowed to use.
The employee themselves opened the session and is sending data within it. Formally, they are not hacking the system or trying to bypass protection. Therefore, familiar control tools may not see exactly what is leaving the network.
The company ultimately lacks answers to basic questions: how many AI services are actually being used, whether credit card numbers, client passport data, API keys for production systems, fragments of proprietary code, etc., are being sent there.
And the scale of what is happening is almost always larger than expected.
Why AI cannot simply be banned
A ban does not eliminate the problem; it eliminates the visibility of the problem. An employee opens an AI service on their personal phone, and now the company has no control over anything.
Moreover, the employee is not a malicious actor: they simply want to do their job faster, and the tool itself encourages sharing context—the more data you provide, the better the response.
Therefore, the task is not to ban AI, but to make its use controllable.
How TETRA Security works
TETRA Security is deployed within the client’s infrastructure and checks every request at the moment of sending—to Claude, ChatGPT, and other AI services.
The system recognizes four categories of data: payment data, personal data, credentials and secrets, source code, and intellectual property. A specific policy is applied to each category—monitoring, masking, or blocking.
Importantly, configuration is done via individual detectors, not by category as a whole. Within payment data, a card number can be masked, while a CVV can be fully blocked—because a masked CVV is useless to anyone, whereas a masked card number still allows the AI to understand the context of the task.
This granularity is what makes the difference between “the system hinders work” and “the system works invisibly.”
Why TETRA Security works on-premise
On-premise is not a technical preference for us, but a market requirement in the region where we operate. Data localization regulations are tightening: the Personal Data Law in Uzbekistan and Kazakhstan, KVKK in Turkey, PDPL in Saudi Arabia and the UAE, and the EU AI Act.
Some cloud-based AI-Security solutions transfer prompts to vendor servers abroad during checking.
For banks or the public sector, under localization requirements, this is a deal-breaker: a protection tool must not itself create cross-border data transfer. Therefore, we initially focused on on-premise deployment—nothing leaves the client’s perimeter.
Why local data matters
We separately invested in local detectors. Global solutions can recognize Visa and Mastercard, but not Uzcard and Humo; they know SSN, but not PINFL in Uzbekistan or IIN in Kazakhstan.
For a bank in Uzbekistan or Kazakhstan, this means that a foreign product will allow through exactly the data that the local regulator considers most sensitive.
How TETRA deployment proceeds
For the first two weeks, we recommend working in observation mode. The system is already deployed and sees everything, but policies are intentionally not enabled—the company first gets a picture: which services are used, by whom, and what data is being sent there.
This report almost always leaves an impression. Management sees not a hypothetical risk from a presentation, but their own documents in someone else’s infrastructure.
After that, the company moves from observation mode to blocking mode.
The order here is crucial—if you start with blocking, you will face resistance from the entire company and gain a reputation as a department that hinders work. If you start with facts, policies are accepted as a logical conclusion from what everyone has already seen with their own eyes.
There is also a side effect that we like even more than the blocking itself. When the system masks a fragment, it explains to the employee exactly what was hidden and why. After a month, employees begin to formulate requests differently—on their own.
Security training is forgotten within a week, but a daily hint at the moment of action works.
What companies should consider when working with AI
Do not start with bans and policies. Start with one question: what is actually happening?
Conduct a week of observation. Most likely, you will see more than you expected—and the decision on policies will follow naturally.
A ban without visibility doesn’t work. And visibility without a ban usually turns out to be the very conversation that changes management’s mind.
First clients
We launched in several large FinTech companies—an industry where the cost of a data error is measured not only by fines but also by licenses.
Live feedback proved more valuable than any hypotheses: based on it, we refined parts of the product. What we considered secondary turned out to be critical for banks, and vice versa.
Example from practice: in one company, during the first week of observation, the InfoSec department discovered that the entire spectrum of work data was being sent to AI chats—from HR certificates to fragments of production code. Not a single intentional violation: employees were simply speeding up their work.
What’s next
Our plan is scaling in Central Asia and the South Caucasus: Azerbaijan, Georgia, Kazakhstan, Kyrgyzstan, Turkey, and Uzbekistan.
The region is convenient because regulatory requirements here are similar, and there are practically no local solutions for this task.
On October 6–7, at the Cyber Security Summit in Tashkent, we will hold our first public launch. Until then, we worked selectively with a limited circle of clients and intentionally avoided a wide announcement—we first wanted to ensure that the product could withstand the companies’ requirements.
Now we are ready to show it directly to CISOs and InfoSec teams in the region.
For publication inquiries, clarifications, and additional materials:
Sardor Ramazon, Chief Product Officer
sardor.ramazon@tetrasecurity.ai
The Tech on Telegram Follow The Tech on Telegram
Keep up with the latest technology and startup news.
Related reading

More from this author

Article Useful
How to protect your accounts from hacking: 8 settings you should check today
The Tech

Article Useful
500 Global: How the Accelerator Works and Who Can Receive Investments
The Tech

Article Interviews
Game Development in Central Asia: Arkady Moldavski on Developing Reverb and the Growth of the Industry
The Tech

Article Useful
Google, Tesla, BlackRock, and the IMF: Where to Apply for an Internship in Fall 2026
The Tech

News IT
Tesla unveiled the flying electric car Roadster
The Tech

News IT
Intero Biosystems startup won the Startup Battlefield at TechCrunch Disrupt 2026
The Tech