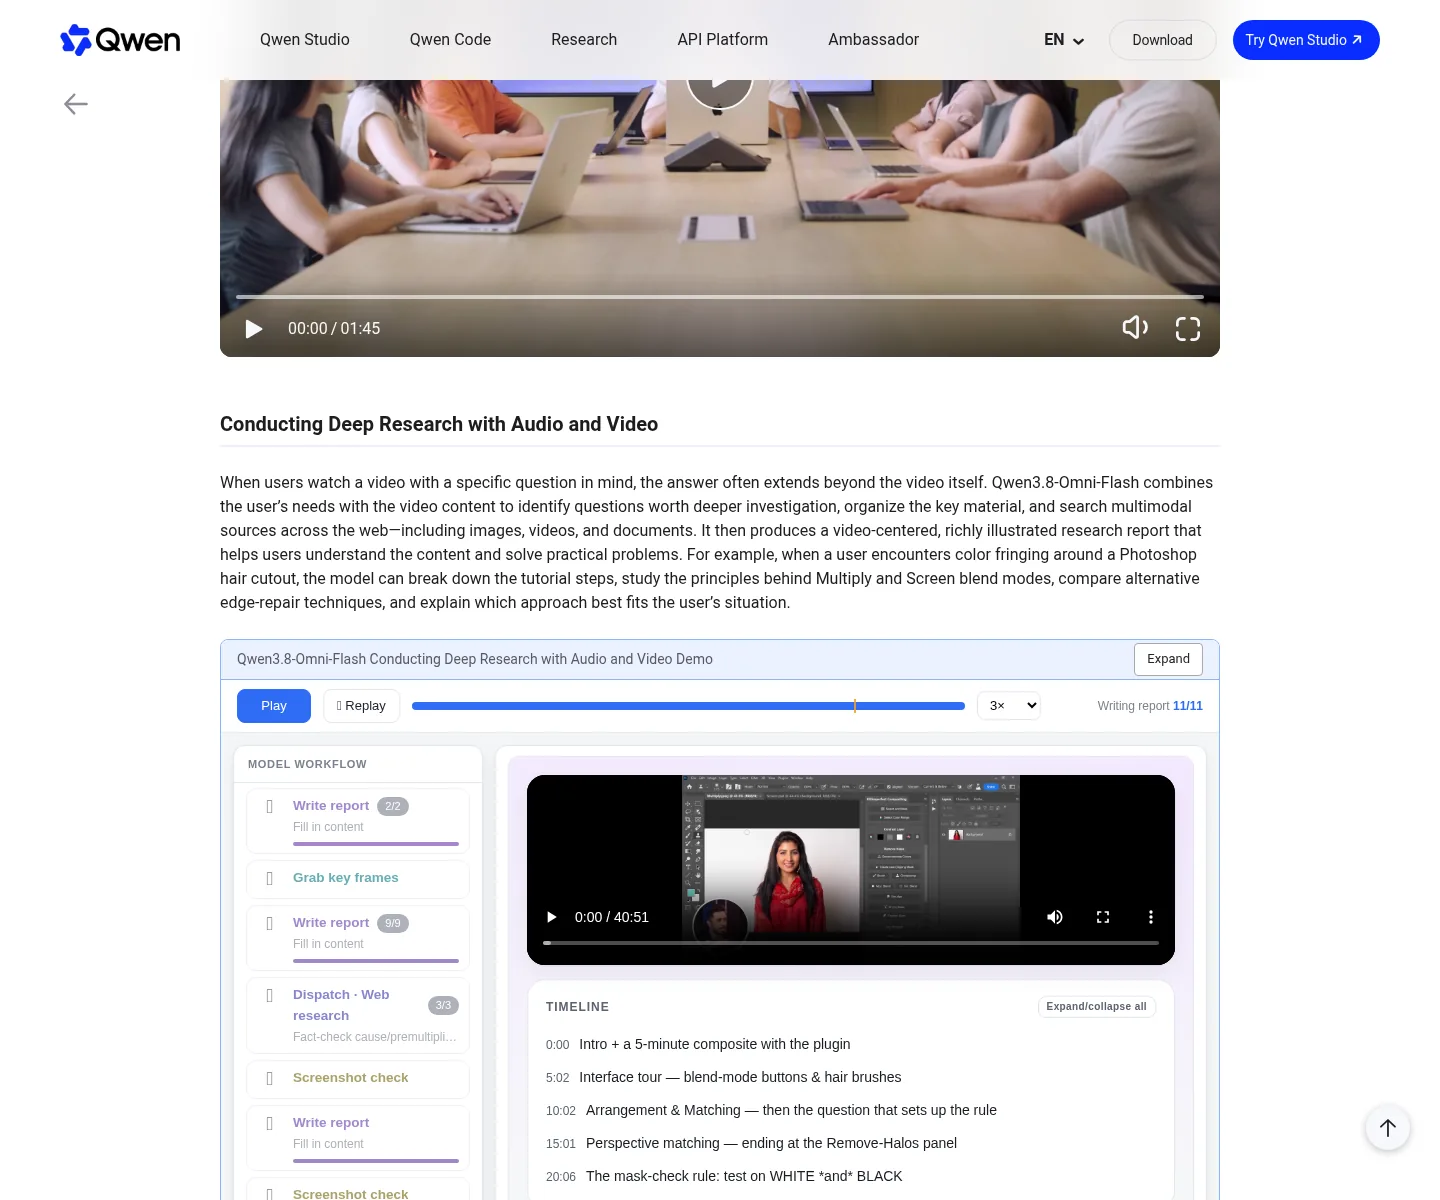
Alibaba has introduced Qwen3.8-Omni-Flash for processing text, audio, video, and images.
The Tech AI
Get the key points in seconds - a short summary from The Tech AI.
Alibaba unveiled the multimodal AI model Qwen3.8-Omni-Flash, featuring a context window of up to 1 million tokens and an agentic understanding mechanism. The cost of processing audio via the API has decreased by more than 98%, and video by 93%, compared to the Qwen3.5-Omni-Plus version. The model supports speech recognition in 74 languages and is available through the API on the Alibaba Qianwen AI platform.
Alibaba has introduced a new multimodal AI model, Qwen3.8-Omni-Flash. It is capable of processing text, images, audio, and video within a single model and supports a context window of up to 1 million tokens.
One of the key changes involves the cost of processing audio and video via the API. According to Alibaba, compared to the previous model Qwen3.5-Omni-Plus, the cost of processing one hour of audio has decreased by more than 98%, and the cost of processing one hour of audio along with video has decreased by more than 93%.
Qwen3.8-Omni-Flash also features an agentic understanding mechanism for handling long audio and video materials. Instead of sequentially processing the entire file, the model identifies which segments need to be analyzed to answer a specific query, and then gradually refines the information.
In the OmniVideoBench test, this approach increased the model's score from 63.4 to 67.8 points. At the same time, the number of tokens used decreased from 145,736 to 79,117, or approximately 45.7%.
According to Alibaba, the average score of Qwen3.8-Omni-Flash increased by more than 25% compared to the previous generation across 29 benchmarks. The model scored 82.7 on LongAudioSpan, which evaluates the understanding of long audio recordings, and 89.7 on AliMeeting for recognizing multi-speaker meetings in Chinese.
Alibaba also stated that the new model outperforms Google's Gemini 3.8 Flash on several tests. The company specifically highlighted results in audio processing and audio-visual tasks.
Qwen3.8-Omni-Flash supports speech recognition in 74 languages and speech generation in 29 languages. Supported languages include Chinese, English, Korean, French, German, and Spanish, while recognition also works with Cantonese, Uyghur, and Maori.
Alongside the model, Alibaba introduced the Qwen-MM-Plugins and Qwen-Live Harness tools. They are designed for creating applications and workflows using audio and video, including video editing, music video creation, translation of short series, analysis of feature films, and converting educational videos into structured notes.
Alibaba also demonstrated an experiment in which Qwen3.8-Omni-Flash was used to improve another AI model. Over 12 hours, the system independently selected data for evaluation, analyzed audio examples, and generated training data to enhance the recognition of the Sichuan dialect in the Qwen2.5-Omni-3B model.
As a result of four rounds of experiments, 3,413 training examples were created, and the recognition error rate decreased from 25.79% to 15.30%.
Qwen3.8-Omni-Flash is already available via API on the Alibaba Qianwen AI platform.
Source: orcarouter.ai
The Tech on Telegram Follow The Tech on Telegram
Keep up with the latest technology and startup news.
Related reading
More from this author

Article Useful
How to protect your accounts from hacking: 8 settings you should check today
The Tech

Article Useful
500 Global: How the Accelerator Works and Who Can Receive Investments
The Tech

Article Interviews
Game Development in Central Asia: Arkady Moldavski on Developing Reverb and the Growth of the Industry
The Tech

Article Useful
Google, Tesla, BlackRock, and the IMF: Where to Apply for an Internship in Fall 2026
The Tech

News IT
Tesla unveiled the flying electric car Roadster
The Tech

News IT
Intero Biosystems startup won the Startup Battlefield at TechCrunch Disrupt 2026
The Tech