OpenAI unveiled Jalapeno — the first chip designed to run AI models
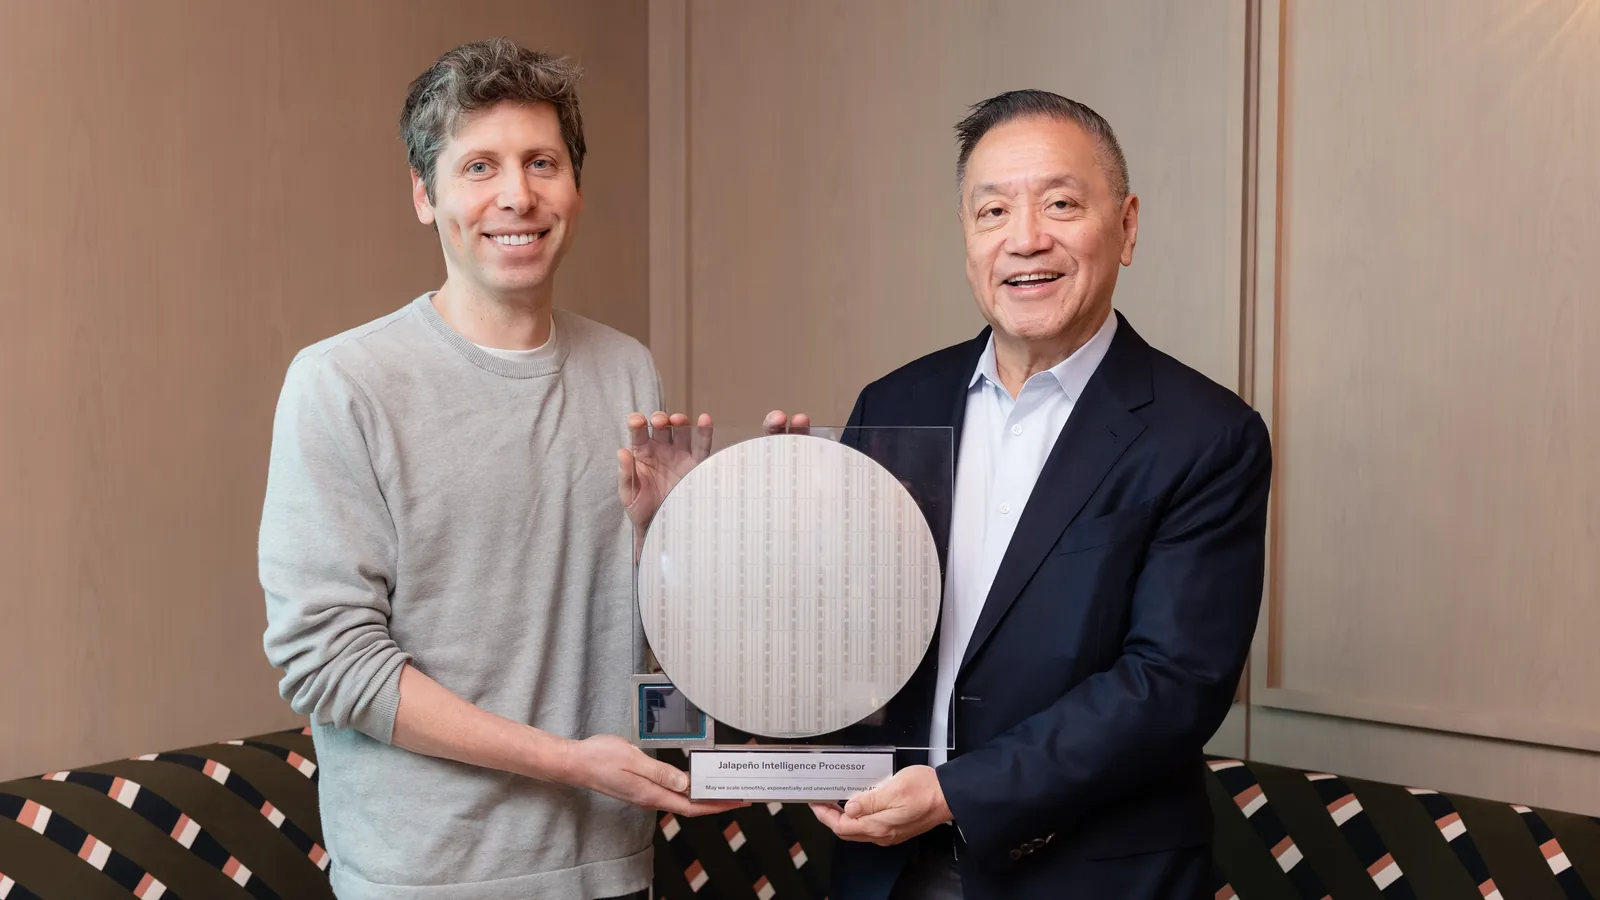
OpenAI, together with Broadcom, has unveiled Jalapeno — the company's first proprietary chip. This is not a processor for training models, but an accelerator for running them. OpenAI is venturing into hardware for the first time: now it produces not only AI and AI-based products, but also the silicon that powers them. Let's take a look at what this chip is and why it matters.
Why OpenAI Needs Its Own Chip
Every AI model operates in two stages. First, it is trained—a process that is expensive and time-consuming, requiring powerful general-purpose processors. Then, the trained model is deployed to respond to user queries—a process known as inference. Inference occurs every time you type something into ChatGPT.
Jalapeno is designed specifically for the second task—running pre-trained models. It is OpenAI’s first Intelligence Processor and the first AI accelerator in the computing platform the company is building in collaboration with Broadcom, planned for several generations ahead.
OpenAI already develops models and products, but now it is taking control of the underlying infrastructure—chip architecture, memory, networking, and deployment systems. By managing the entire stack, each layer can be optimized for a single goal: making models faster, more reliable, and cheaper.
What Is Jalapeno?
This is a chip designed from scratch for modern LLM inference, rather than repurposed from a general-purpose accelerator for older tasks. OpenAI developed it based on how its own systems—ChatGPT, Codex, the API, and future agentic products—actually operate. At the same time, the chip is designed to work with any language models, not just OpenAI’s own.
OpenAI designed the chip independently, while partners helped bring it to production: Broadcom is responsible for silicon implementation and networking technologies, including Tomahawk network chips, while Celestica handles boards, racks, and system assembly.
Nine-Month Development Cycle
The most notable aspect of this story is the timeline. The journey from initial design to tape-out—the stage where the design is ready for manufacturing—took just nine months. OpenAI believes this may be the fastest ASIC chip development cycle in the history of high-performance semiconductors, where development typically takes years.
The development was accelerated by OpenAI’s own models. They were used in certain stages of design and optimization. In other words, the models that the company releases to users are now helping to build the infrastructure for launching the next generation of models.
What Is Already Working
Engineering samples of Jalapeno are already handling real ML workloads in the lab—at target clock speeds and power levels. Among the models already running is GPT-5.3-Codex-Spark.
Early tests indicate that the chip will deliver performance per watt “significantly higher” than current leading solutions. Final performance metrics are still being measured by OpenAI, and a detailed technical report is expected to be published in the coming months.
The technical advantage is attributed to an architecture that reduces data movement and balances computation, memory, and networking—allowing actual hardware utilization to approach theoretical limits.
Why This Matters
Inference is the stage where AI directly interacts with users. Therefore, improvements in cost, speed, and reliability at this level directly impact end products: ChatGPT responses arrive faster, Codex tasks execute more steps with less waiting, API-based products become cheaper to develop, and service access remains stable during peak traffic hours.
OpenAI describes this as a closed loop: more advanced infrastructure improves computational efficiency, which leads to better model training and deployment; stronger models form the foundation for better products; and increased usage and revenue enable reinvestment in the next generation of infrastructure.
The Tech on Telegram Follow The Tech on Telegram
Keep up with the latest technology and startup news.
Related reading




More from this author

Article Useful
How to protect your accounts from hacking: 8 settings you should check today
The Tech

Article Useful
500 Global: How the Accelerator Works and Who Can Receive Investments
The Tech

Article Interviews
Game Development in Central Asia: Arkady Moldavski on Developing Reverb and the Growth of the Industry
The Tech

Article Useful
Google, Tesla, BlackRock, and the IMF: Where to Apply for an Internship in Fall 2026
The Tech

News IT
Tesla unveiled the flying electric car Roadster
The Tech

News IT
Intero Biosystems startup won the Startup Battlefield at TechCrunch Disrupt 2026
The Tech